Model assistance is presented as the answer to the cost of video annotation. It delivers a real gain, it moves the work rather than removing it, and it introduces failure modes manual production does not have.
This article sets out what it does and what it demands. It extends the article on preparing a video dataset.
The three levels of assistance
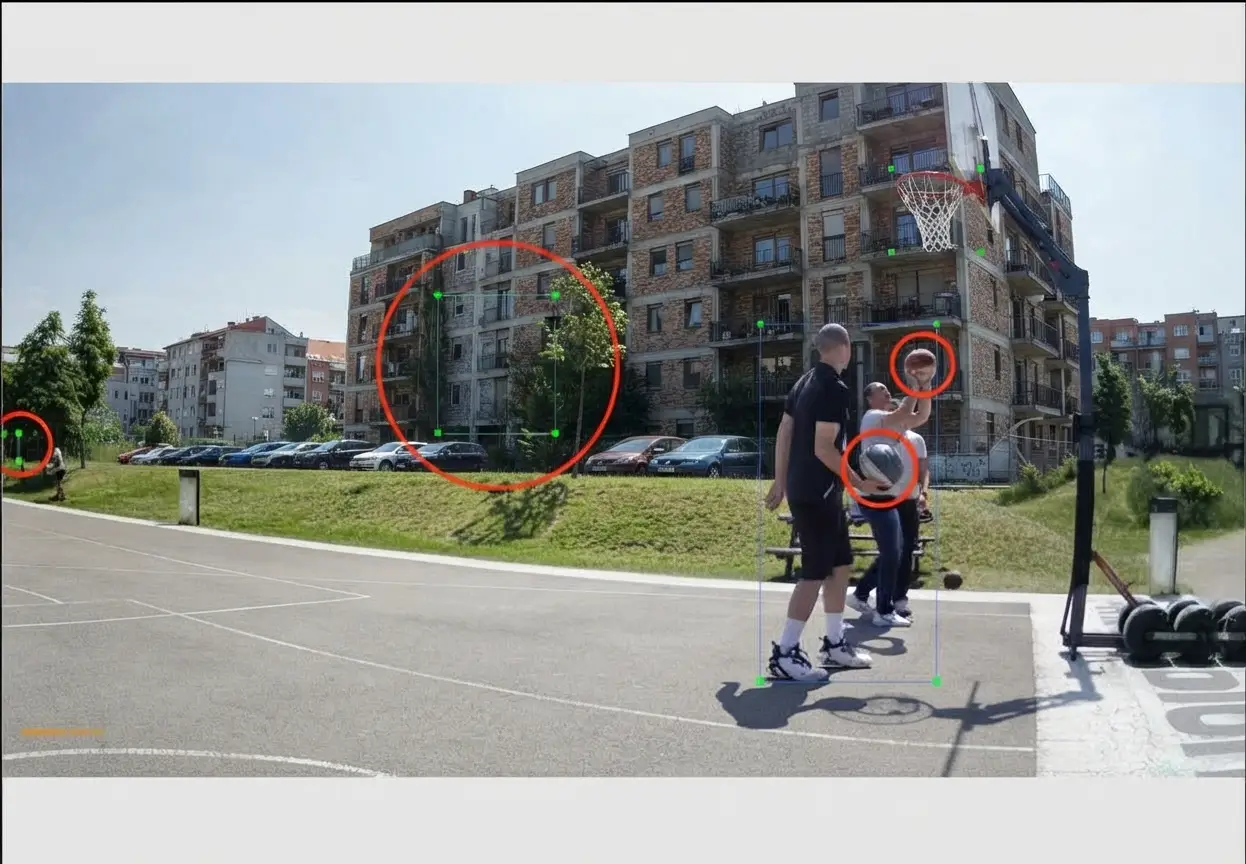
Three mechanisms are distinguishable in video annotation. Their confusion produces inaccurate expectations. Geometric interpolation, which computes intermediate positions without looking at the frames and whose behaviour is entirely predictable. Assisted tracking, which analyses the frames to extend a track and whose errors depend on the content. And full pre-annotation, where a model produces a first set the annotator corrects. One important practical consequence follows. Those three mechanisms do not demand the same thing, the first requiring no model and the third presupposing an initial corpus, which makes them available at different moments in a video annotation project.What assistance actually delivers
Four effects of assistance are measurable. They do not bear on the same thing. Throughput rises on common configurations, which represent most of the duration. Consistency improves, a model applying the same rule everywhere where several annotators vary. Disagreements between the model and the annotator locate the difficult configurations. And the marginal cost of an additional batch falls once the conventions are established. One important observation follows. The second effect is the least expected and it counts as much as the first, a consistent pre-annotation reducing inter-annotator variability on the cases where the convention is clear.What assistance does not do
Four limits bound what assistance contributes. They are structural. A model has no more information than an annotator on an undecidable case, which produces a confident and unfounded decision. It applies the conventions of the corpus that produced it, which makes a pre-annotation unusable where the rules have changed. It does not detect what it has never seen, which leaves the rare classes entirely to the human. And it does not adjust temporal boundaries with the precision a measurement requires. One practical consequence follows for a video annotation project. The third limit is the most consequential, assistance being weakest exactly on the configurations a corpus most needs.Validation bias
This mechanism silently degrades quality. It is specific to this way of working. Accepting a proposal takes less effort than producing an annotation. Three manifestations follow in video annotation. An approximate box is validated where the annotator would have produced a better one. A plausible class is accepted without the alternative being examined. And an identity link is confirmed while resting on the same inference the annotator would have made. One important observation follows. Those three manifestations produce a corpus that appears more consistent and reproduces the model’s errors, which makes periodic measurement on unassisted batches indispensable rather than optional.Error propagation
This second mechanism is specific to video annotation. It aggravates the preceding one. A tracking error continues until a check stops it. Three consequences follow. A switch at an occlusion contaminates every subsequent frame of the track. Correction requires redoing a whole segment rather than one frame. And sampled validation has a high chance of missing the tipping point while meeting its consequences. One important practical consequence follows for a video annotation project. Those three consequences require concentrating verification at the break points, occlusions and crossings, rather than spreading it uniformly over the duration.The improvement loop
This organisation turns assistance into a growing lever. It is set up from the first batch. Each corrected batch feeds the model that will pre-annotate the next. Four stages compose that loop. Pre-annotation of the batch by the current model. Correction by the annotators, with disagreements recorded. Retraining on the enriched corpus. And analysis of the disagreements, which directs the next batch’s content. One observation follows. The fourth stage is what distinguishes a loop from a mere repetition, the disagreements locating what the model does not master and therefore what it must be given.What the model learns from the corpus
One property of the loop deserves flagging since it produces a cumulative effect. A model retrained on a corrected corpus reproduces that corpus’s conventions. Three consequences follow. The project’s conventions propagate into the proposals, which makes assistance progressively more relevant. Uncorrected systematic errors reinforce, the model learning a wrong rule applied with consistency. And a convention change mid-project creates an inconsistency between the older batches and the current model. One important practical consequence follows for a video annotation project. The second consequence justifies the unassisted share well beyond a simple drift measurement, a fully assisted corpus ending up validating its own errors with nothing signalling it.When assistance becomes available
A calendar constraint structures this video annotation arrangement. A useful pre-annotation presupposes a model, which presupposes a corpus. Three phases succeed one another in an assisted video annotation project. The start, where only geometric interpolation is available and where the cost per object is at its maximum. The ramp, where a first model produces imperfect proposals whose correction still costs time. And the established regime, where the model handles most of it and the human concentrates on the difficult cases. One practical consequence follows. This progression explains why a long project is proportionally cheaper than a short one, and it justifies proposing a multi-year engagement rather than a succession of one-off orders.The bootstrap corpus
A practical question arises at the start and it admits three answers. A model needs a first corpus to be useful. Three sources permit obtaining that bootstrap corpus. Manual annotation of a first batch, a safe method and the most expensive. A pre-trained generalist model, which detects common classes and ignores domain classes. And a public corpus from the same domain, which gives a starting point and requires the conventions to be checked. One important observation follows for a video annotation project. The second source is the most used and it produces a side effect, a generalist model steering annotators towards its own categories rather than towards the project’s nomenclature, which requires checking the correspondence before using it.The confidence threshold
One setting determines what the model proposes and it is rarely examined. A pre-annotation presents only the detections above a given score. Three threshold regimes are distinguishable in video annotation. A high threshold proposes only the certain cases, which produces few corrections and leaves much to produce manually. A low threshold proposes more and increases the work of removing wrong proposals. And an intermediate threshold seeks the point where the time gained exceeds the time correcting. One important practical consequence follows. That point is measured on a sample rather than guessed, and it differs by scene type, which justifies a differentiated threshold rather than one value applied to a whole corpus.Measuring what assistance delivers
Four indicators quantify the gain, and they are read with no particular effort. Time per object with and without assistance, measured on the same sequence type. The rate of proposals accepted without modification. The rate of proposals corrected, which distinguishes help from hindrance. And agreement on unassisted batches, which detects any quality drift. One practical consequence follows. The third indicator deserves particular attention, a high correction rate meaning the annotator spends more time repairing than they would gain producing, a situation where assistance should be switched off rather than improved.What stays human
Five decisions cannot be delegated in video annotation. They define the competence expected. Judgement on an undecidable case, where the model produces a certainty the data does not carry. Identity linking after a prolonged occlusion. Adjusting temporal boundaries, which assistance locates without refining. Flagging a case the convention does not cover. And the decision to discard a whole proposal rather than correct it. One important observation follows for a video annotation project. The last decision is what distinguishes a trained annotator, redoing a badly proposed segment from scratch often costing less than correcting an unsuitable proposal.Training annotators for assisted work
Five reflexes distinguish an annotator trained for this mode and they are not acquired by use. Examining before accepting, the natural reflex being to validate what looks plausible. Recognising the configurations where the model systematically fails, occlusions and crossings first among them. Discarding a whole proposal rather than correcting it where it is unsuitable. Flagging a recurring model error rather than silently correcting it at each occurrence. And keeping the same standard on unassisted batches, whose lower throughput must not translate into different quality. One practical consequence follows for a video annotation project. The fourth reflex is the most useful collectively, a systematic error flagged once being corrected at retraining where it otherwise costs one correction per occurrence indefinitely.What assistance changes in the control
Four adaptations of the control arrangement are required in assisted video annotation. Sampling must target the break points rather than spread uniformly. A share of batches must stay unassisted to measure drift. The model’s systematic errors must be sought specifically, a consistent confusion passing every formal check. And the correction rate must be tracked by configuration type, its rise signalling a change in the content or a degradation of the model. One practical consequence follows. The second adaptation costs part of the gain and it constitutes the only reliable measure of real quality, which makes it non-negotiable rather than optional.What assistance changes in the costing
Four cost effects accompany this arrangement and two of them run against intuition. The cost per object falls on common configurations, an expected and real effect. The setup cost is added, model integration and threshold tuning. Control becomes more expensive, the unassisted share and the search for systematic errors adding to the ordinary arrangement. And the cost varies over time, the first phase being dearer than the following ones. One observation follows for a video annotation project. Those four effects make a fixed price on a short project particularly risky, the gain not having time to offset the setup, which argues for reserving assistance for long engagements.The generalist models
One development modifies the starting point and its effect deserves situating. Models trained on very large corpora segment or track with no specific training. Three contributions are real and verifiable in video annotation. Segmentation from a point or a box, which replaces a manual outline with a designation. Tracking a designated object across a sequence, with no prior corpus. And immediate availability, which removes the bootstrap phase. Three caveats accompany them. The domain nomenclature stays absent, a generalist model separating objects without knowing which ones matter. Performance falls on small, blurred or unusual objects. And identity consistency over a long sequence remains the weak point. One important observation follows. These models move the effort from outlining towards designation and verification, which improves segmentation tasks above all and leaves identity tracking in the state this chapter described.When to abandon assistance
Four situations make this arrangement counterproductive and it is better to recognise them early. A corpus too small, where setup and bootstrapping exceed the expected gain. Highly heterogeneous content, where the model never meets the same configuration twice. A nomenclature still stabilising, a pre-annotation fixing conventions the project is in the middle of revising. And a high precision requirement on boundaries, which assistance locates without refining. One observation follows for a video annotation project. The third situation is the most frequent at the start, which justifies producing the first batches manually until the conventions hold, rather than introducing an assistance that will reproduce rules due to change.The minimal arrangement
Five measures frame an assisted chain and their cost stays modest. A share of unassisted batches, fixed at the outset and maintained throughout the project. Tracking the correction rate by configuration type. Targeted verification at the break points, occlusions and crossings. Searching for the model’s systematic errors, distinct from the formal check. And the instruction to flag recurring errors rather than silently correct them. One observation follows for a video annotation project. Those five measures consume part of the announced gain and they are what distinguishes an assistance that improves a corpus from one that degrades it by making it faster.What to tell the client
Four framings make this conversation honest and they avoid an untenable promise. Announce a gain on common configurations rather than a global gain, the distinction being verifiable and the global promise not. Set out that control changes nature rather than disappearing, the unassisted share being a new expense. Situate the gain in time, the first phase being more expensive than manual production on a short project. And recall that rare classes stay with the human, which bounds the saving on the corpora where that is the issue. One observation follows for a video annotation provider. The second framing is the one most readily omitted and the one that best protects, a client discovering mid-project an unannounced control line concluding that the gain was overstated.Approaching an assisted project
Five questions scope an assisted video annotation arrangement. Does a model exist or must one be bootstrapped. That answer determines when the gain arrives. Do the model’s conventions match the project’s. A divergence makes pre-annotation counterproductive. Is an unassisted share planned. Its absence makes drift undetectable. Will the correction rate be tracked. Its rise signals that assistance should be switched off rather than pushed. And is the retraining loop organised. Its absence turns a growing lever into a fixed gain. Those five answers determine the real gain. Asking them before starting avoids a promise of saving the arrangement will not keep.The question that decides on assistance
One question settles whether this arrangement is worthwhile and it concerns the project rather than the technique. Will the corpus be produced once or enriched over time. A single short production makes assistance doubtful, setup and bootstrapping consuming the gain before it appears. A durable enrichment makes it decisive, each batch improving the model that will handle the next. That question is asked at scoping, it determines whether assistance is an investment or an expense, and it explains why the same arrangement is profitable at one client and not at another.Three precautions before launching
Three precautions distinguish a sound assisted chain from one that drifts. Fixing the share of unassisted batches before the first batch, a value that is not renegotiated later under schedule pressure. Verifying that the model’s conventions match the project’s, a divergence producing more correction work than production work. And waiting until the nomenclature is stable before introducing pre-annotation, a model fixing rules under revision. Those three precautions cost little, they are taken at scoping, and their absence produces a fast chain whose quality nobody can any longer establish.What this chapter teaches
One cross-cutting observation deserves closing this examination. Assistance moves the work upwards rather than reducing it. Three findings compose it. It handles the common configurations and leaves intact those that make a corpus difficult. It introduces two failure modes of its own, validation bias and propagation, which call for a specific control consuming part of the gain. And it requires a more competent annotator, able to recognise an unsuitable proposal rather than correcting it mechanically. That finding matches the one the preceding series established about assistance tools in very different domains: they accelerate the easy work and leave the hard work intact, which makes their contribution real and their effect on total cost more modest than announced.What a client sees and what it means
One perception problem deserves naming, since it shapes how assisted work is judged. A client watching assisted annotation sees a fast, smooth process and concludes the work is easy. Three consequences follow from that impression of video annotation. The price is questioned, the visible effort having fallen while the invoice has not fallen proportionally. The control lines look like padding, since nothing visible suggests they are needed. And the difficult cases become invisible, an annotator spending ten minutes on one occlusion looking slower rather than more careful. One practical response exists for a video annotation provider. Show the correction rate alongside the throughput, since the two together describe what is happening where either alone misleads, and a client who sees that a third of proposals required correction understands why the human step is not a formality.Common mistakes
These failures recur often enough that naming them is usually enough to avoid them.- Confusing interpolation, assisted tracking and full pre-annotation.
- Promising a gain equal to the rate of accepted proposals.
- Using a model whose conventions differ from the project’s.
- Keeping no unassisted batches to measure drift.
- Spreading verification uniformly rather than at the break points.
- Neglecting to track the correction rate.
- Expecting assistance to handle the rare classes.
- Mechanically correcting a proposal that should have been discarded.
- Omitting the retraining loop, which makes the gain grow.
- Assuming that a consistent pre-annotation is a correct one.