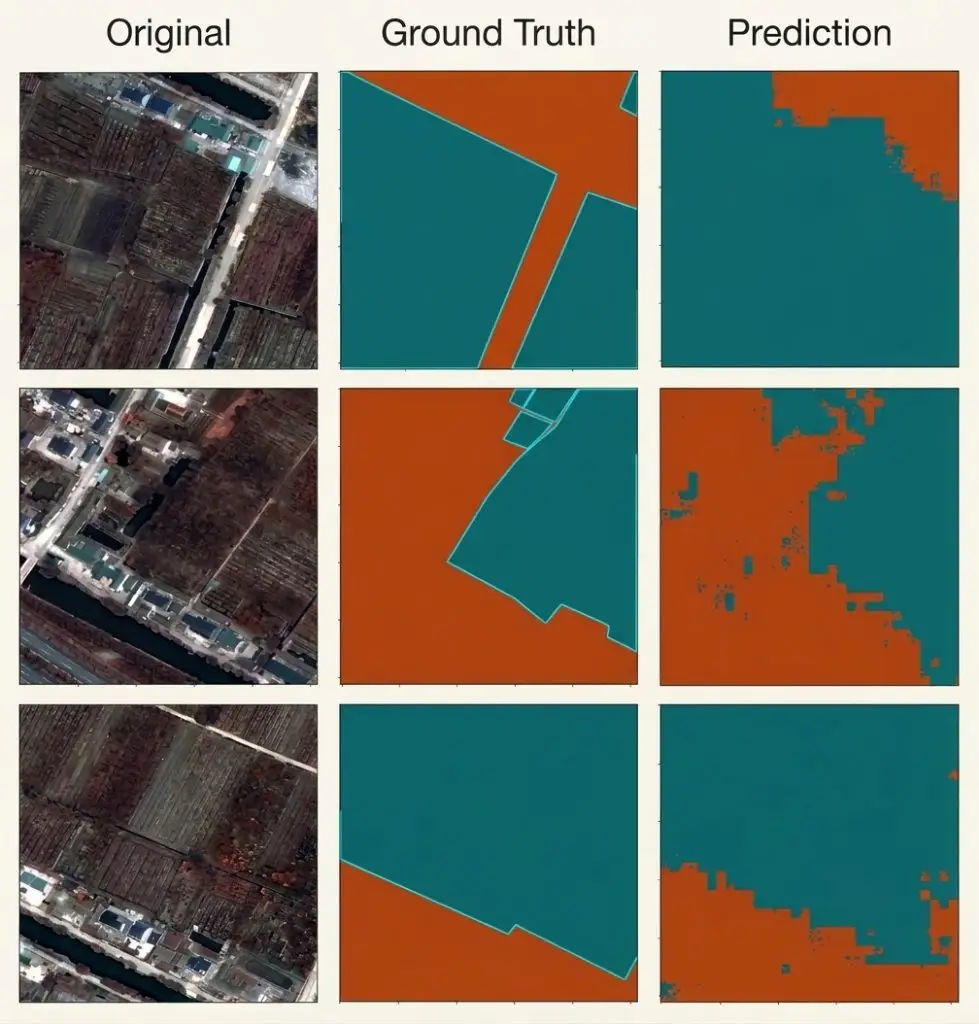
The twelve preceding articles in this series on satellite image segmentation covered classes, modalities, tools and errors. This one gathers those elements into a method for building a corpus, from scoping to delivery.
One observation structures it: the order of operations matters as much as their content, several decisions becoming impossible to take once production has begun. It extends the article on errors in satellite segmentation.
The eight stages of building a corpus
Their sequence conditions the result as much as their execution. Scoping establishes the operational question, the resolution needed and the feasibility. Design defines the nomenclature, the conventions and the sampling plan. The pilot tests those definitions on a small sample and establishes a throughput. Preparation acquires the imagery, corrects it and cuts it into batches. Production annotates under the established protocol. Checking verifies, corrects and measures the quality obtained. Validation builds the evaluation set and measures what is achievable. And delivery assembles the corpus, its documentation and its metadata.Scoping
Four questions determine the feasibility of a satellite image segmentation project. They are asked in a single meeting. What decision will depend on this corpus, a framing that determines the nomenclature and eliminates classes nobody has a use for. Are the target objects visible at the accessible resolution, a question the several-pixels rule settles immediately. Is the information sought contained in the intended imagery, the cover and use distinction the nomenclature article drew. And what ground truth exists or can be built, the limiting factor the previous series documented. A negative answer to any of those four stops the project or redefines it, and obtaining it now costs a meeting where obtaining it later costs the project.Design
This stage produces the documents that govern everything else. It generally takes a few days. The nomenclature defines the classes by observable and quantified criteria, with their hierarchy, the priority rules and the minimum mapping unit. The geometric conventions fix the position of limits on gradual transitions, the treatment of mixed pixels and that of boundary elements. The sampling plan determines which areas will be annotated, under what stratification and with what inclusion probabilities, a requirement the validation article in the previous series presented as non-negotiable. And the technical specifications fix the format, the projection, the chip size and the metadata to retain. One observation runs across those four documents. They are written before production and they are modified only with great difficulty afterwards, a change invalidating work already produced.The pilot
This stage separates a theoretical design from an applicable protocol. Its omission is the commonest error in satellite image segmentation. The principle is to have a small representative sample annotated by several people independently, under the project’s real conditions. Five pieces of information follow. A measured throughput, turning a cost estimate into a defensible figure. The agreement rate between annotators, which bounds achievable performance. The list of ambiguous cases, which feeds the case library. The gaps in the nomenclature, revealed by the questions asked. And validation of the technical arrangement, a format problem manifesting immediately. One important consequence follows for a corpus. High disagreement does not indicate poor annotators but insufficient definitions, and the response is to sharpen rather than to replace. That stage takes days on a project spanning months, and it is the only way to establish that a protocol works before committing a budget to it.Data preparation
Six operations compose this technical stage, whose defects propagate silently. Selecting acquisitions under date, cloud cover and configuration criteria. Geometric correction and verification of alignment between sources. Radiometric harmonisation where several acquisitions are combined. Cutting into chips with overlap. Assigning batches to annotators. And retaining the metadata associated with each chip. One verification deserves treating as mandatory. Checking alignment between the annotated imagery and any reference used avoids a systematic offset that will later be attributed to the annotation or to the model, a difficulty the boundary article detailed.Production
This stage represents most of the volume. Its quality depends on organisation more than on individuals. Four arrangements support it. The case library accessible during the work, not consulted at the start then forgotten. A channel for raising new cases, any case not covered being arbitrated and added to the library rather than settled individually. Throughput tracking per annotator, which reveals a local difficulty or a drift before it affects substantial volume. And periodic calibration sessions, where several annotators handle the same sample and compare, which maintains consistency over time. That fourth arrangement is the most neglected and the most useful on a long project. Consistency degrades naturally over time, each annotator refining their own interpretation, and only regular recalibration maintains it.Quality control
This stage is not reducible to a reread. Its organisation determines its effectiveness. Three modes combine usefully. Automatic systematic checking verifies what is verifiable without judgement: topology, valid class values, absence of gaps, compliance with the minimum unit. Targeted checking preferentially examines boundary zones and configurations identified as difficult, which the boundary article showed markedly more productive than random sampling. And light random checking supplies an estimate of overall quality that targeted checking does not give. An independence requirement accompanies those three modes. A checker must not verify their own work, an annotator naturally validating their own logic.Validation
This stage is distinct from production. Its quality requirement is higher. Four principles govern it. The evaluation set is built on areas and periods distinct from training, a geographic rather than random split. It is produced under a documented probabilistic plan, with stratification where rare classes are involved. It is handled with greater care, multiple reading and documented arbitration on ambiguous cases. And annotator disagreement is measured on it separately for boundaries, which supplies the relevant bound. One counterintuitive recommendation follows. Concentrating expert effort on a restricted evaluation set is better than spreading it evenly across a wide corpus, the reference quality bounding what any measurement can establish.Sizing a corpus
This question rarely receives a founded answer. It nonetheless precedes production. Three approaches permit estimating the volume needed and their reliability differs. The empirical per-class rule fixes a minimum number of examples for each category, increasing substantially for rare classes and difficult distinctions. The learning curve trains the model on increasing fractions of the available corpus and observes where performance stops improving, a reliable method presupposing part of the corpus already exists. And active annotation builds the corpus progressively, selecting at each iteration the examples the model hesitates on, which reduces the volume needed at equal quality. One observation runs across those three approaches. The volume needed depends more on the diversity covered than on the raw number of examples, a thousand varied examples being worth more than ten thousand similar ones in satellite image segmentation. One practical consequence follows. The sampling plan matters more than the target size, and a project unable to answer the volume question gains from starting small and measuring rather than estimating generously.Delivery
This stage determines what the corpus will permit. It is regularly rushed. Six elements make up a complete delivery. The annotations themselves, in both raster and vector formats where both are useful. The nomenclature document with its definitions and its illustrated case library. The composition documentation, indicating the distribution by region, by season, by source and by class. The acquisition metadata associated with each element, date, sensor and processing level. The quality report, with the measured agreement rates and the checking method used. And the exclusion log, listing what could not be annotated and why. That last element is the most often omitted and it distinguishes a known gap from an invisible one, which changes the corpus’s value for any later use.The role of the domain expert
This constraint determines the quality of everything above. It is poorly managed in most satellite image segmentation projects. A nomenclature is not designed from imagery alone. It requires someone who knows the ground and the use, and who can settle what observation leaves undecidable. Four interventions belong specifically to that person. Validating the relevance of the classes to the use. Arbitrating edge cases on real examples. Verifying the operational definitions, a definition potentially seeming clear to a technician and inapplicable to someone who knows the variety of situations. And arbitrating new cases raised during production. One practical difficulty accompanies that requirement. Such a person is generally scarce and busy, and their time is the limiting factor of the design phase rather than the annotation budget. One organisational consequence follows. Concentrating their involvement on the structuring decisions, presenting prepared cases rather than an open question, obtains the essentials in hours where an unprepared approach would consume days.Tracking consistency over time
This difficulty escapes point-in-time checks. It is specific to long projects. A corpus’s consistency degrades naturally over months, with no individual error being committed. Three mechanisms produce it. Each annotator progressively refines their own interpretation of the rules, which slowly separates practices. New cases settled along the way are not always relayed to others. And staff rotation introduces different interpretations nothing recalibrates against the earlier ones. Three arrangements respond. Periodic calibration sessions, where several annotators handle the same sample and compare results. Re-annotating an older sample at regular intervals, which directly measures the drift. And genuinely updating the case library, each new arbitration being recorded and circulated. That second arrangement is the most informative and the least practised in satellite image segmentation. Re-annotating today a batch handled six months earlier reveals a discrepancy nothing else shows, and that discrepancy is the most direct measure of a corpus’s internal consistency.The trade-offs to settle
Five structuring decisions condition an entire satellite image segmentation corpus. They arise at scoping. Volume against quality. A larger and less consistent corpus is worth less than a smaller regular one, the disagreement bound applying to the whole. Breadth against depth. Covering several regions superficially or one completely answers different needs, geographic transferability being limited. Training against evaluation. The allocation of effort between the two generally favours the second beyond what intuition suggests. Automation against control. Pre-annotation accelerates training and must be proscribed for the evaluation reference. And exhaustiveness against sampling. Scale forbidding exhaustiveness, the quality of the sampling plan replaces complete coverage and must be documented.Documentation as a deliverable in its own right
It conditions a corpus’s value more than its volume does. Five documents accompany it and each answers a distinct question. The nomenclature document answers what each class denotes, with quantified definitions and an illustrated case library. The method document answers how the corpus was produced, sampling plan, annotation protocol and checking arrangement. The composition document answers what the corpus covers, by region, season, source and class. The quality report answers what can be expected of it, measured agreement rates and identified limits. And the exclusion log answers what is missing and why. One common property makes those five valuable beyond the project. They are written during the work at marginal cost and they cannot be reconstituted afterwards, a principle every cluster in this series established and which finds here its most direct application.The corpus as an asset
One reading completes this method because it changes how the effort should be conceived. A correctly documented satellite image segmentation corpus retains its value beyond the project that produced it, for three reasons. The underlying imagery does not expire, the public archive remaining accessible indefinitely, which permits re-examining a corpus years later. The ground truth records what was on the ground, information no later model renders obsolete. And a documented corpus extends, a second project adding to it rather than restarting. Two conditions govern those three properties and both are cheap. The documentation must exist, an undocumented corpus losing its value when those who produced it leave. And the reference must be kept separately from model outputs, a project storing predictions rather than observations having stored something that ages.The typical satellite image segmentation calendar
An indicative distribution helps at scoping, subject to everything depending on the project. Scoping and design represent days and they determine the ceiling of everything else. The pilot represents further days and it turns estimates into measurements. Preparation represents a modest and automatable share after the first project. Production represents most of the duration and its estimate follows from the pilot. Checking represents a fraction of production, generally underestimated. And validation represents a small volume and a concentrated expert effort. One observation runs across that distribution. The stages determining quality represent a fraction of total time and they are precisely those schedule pressure leads to compress.Adapting the method to project size
One qualification deserves making, the complete method being disproportionate for some projects. Three levels of requirement are distinguishable and confusing them leads to over-equipping an exploration or under-equipping a production. An exploratory project retains the scoping, a simple nomenclature and a modest evaluation set, refraining from claiming more than that supports. An operational product retains the whole method, the decisions committing a real use. And a product under contractual or regulatory requirement adds the traceability and auditability the previous series detailed. One observation runs across those three levels. Two stages never reduce, whatever the level adopted: the four-question scoping, which costs a meeting, and the written boundary convention, which costs an hour and determines the ceiling.What this method teaches
One cross-cutting observation deserves closing this examination because it summarises the thirteen preceding articles. The method set out contains no technically difficult operation. Each stage is simple to describe and most execute without rare competence. Its difficulty is entirely disciplinary. It consists of doing things in an order whose usefulness appears only afterwards, and of spending time on invisible deliverables before producing what the sponsor expects. Three consequences follow for a provider. The value brought lies not in an inaccessible technique but in a discipline schedule pressure discourages, which makes it defensible to a client who understands the mechanism. That discipline is demonstrated through documents rather than assertions, which makes it verifiable and therefore credible. And it compounds, method documents and case libraries carrying from one project to the next, which lowers the cost of rigour as it becomes a habit.Where the effort actually goes
One accounting of satellite image segmentation effort deserves setting out, since the intuitive allocation and the productive one differ. Intuition allocates effort proportionally to volume: most of it to production, since that is where the objects are annotated. The productive allocation weights differently, and four adjustments account for most of the difference. More to design than feels warranted, since the documents produced there govern every subsequent hour and cannot be revised cheaply. More to the pilot than its duration suggests, since it converts every downstream estimate from guess to measurement. More to validation than its volume implies, since the reference quality bounds what any figure can mean. And more to documentation than it appears to deserve, since it is the only part that survives the project. The common thread is that the stages worth over-resourcing are the ones producing no visible output, and the stage worth resisting the urge to expand is the one producing the most. That inversion is uncomfortable to defend and it is the whole practical content of this method. A project that reallocates even modestly in that direction outperforms one that allocates by volume, at the same total cost.Common mistakes
These failures recur often enough that naming them is usually enough to avoid them.- Launching production before testing the nomenclature through a pilot.
- Modifying the nomenclature during production.
- Sampling by availability rather than under a documented plan.
- Building the evaluation set on the same areas as training.
- Making the case library inaccessible during the work.
- Omitting calibration sessions on a long project.
- Having work checked by whoever produced it.
- Checking by random sampling only.
- Delivering without composition documentation.
- Omitting the exclusion log.
- Estimating a target volume rather than measuring a learning curve.
- Never re-annotating an older sample to measure drift.