Autonomous driving is the vertical that has most shaped video annotation practice. It produced the reference datasets, the formats and the metrics other fields adopted afterwards. It also presents constraints no other sector combines.
This article sets out what this context requires and what it teaches. It extends the article on interpolation and keyframes.
What distinguishes this context
Five properties separate it from the other video annotation verticals. The viewpoint is mobile, the carrying vehicle moving at the same time as the objects observed. The sensors are multiple, cameras, radar and LiDAR supplying views to be registered against one another. The consequence of an error is bodily, which moves the requirement outside the economic domain. The volumes are considerable, a fleet of instrumented vehicles producing more data than any organisation can annotate. And the regulatory framework is being built, the type approval of automated systems imposing unprecedented traceability requirements. One important practical consequence follows. Those five properties compound, which makes this the most demanding vertical in video annotation and explains why its practices spread elsewhere.What the mobile viewpoint changes
This property modifies several arguments from the preceding articles. Every object appears to move in the image, including those stationary on the ground. Four consequences follow. Interpolation in the image frame becomes unreliable, a fixed object following a complex apparent trajectory. The distinction between a moving and a stationary object is not directly observable and nonetheless constitutes essential information. Occlusions become frequent and brief, the carrier’s movement constantly passing objects behind others. And the change of scale is rapid, an approached object seeing its size vary strongly across few frames. One important observation follows. The first consequence justifies working in an absolute frame whenever the carrier’s trajectory is known, which restores the regularity of movement and makes interpolation usable.The objects to annotate
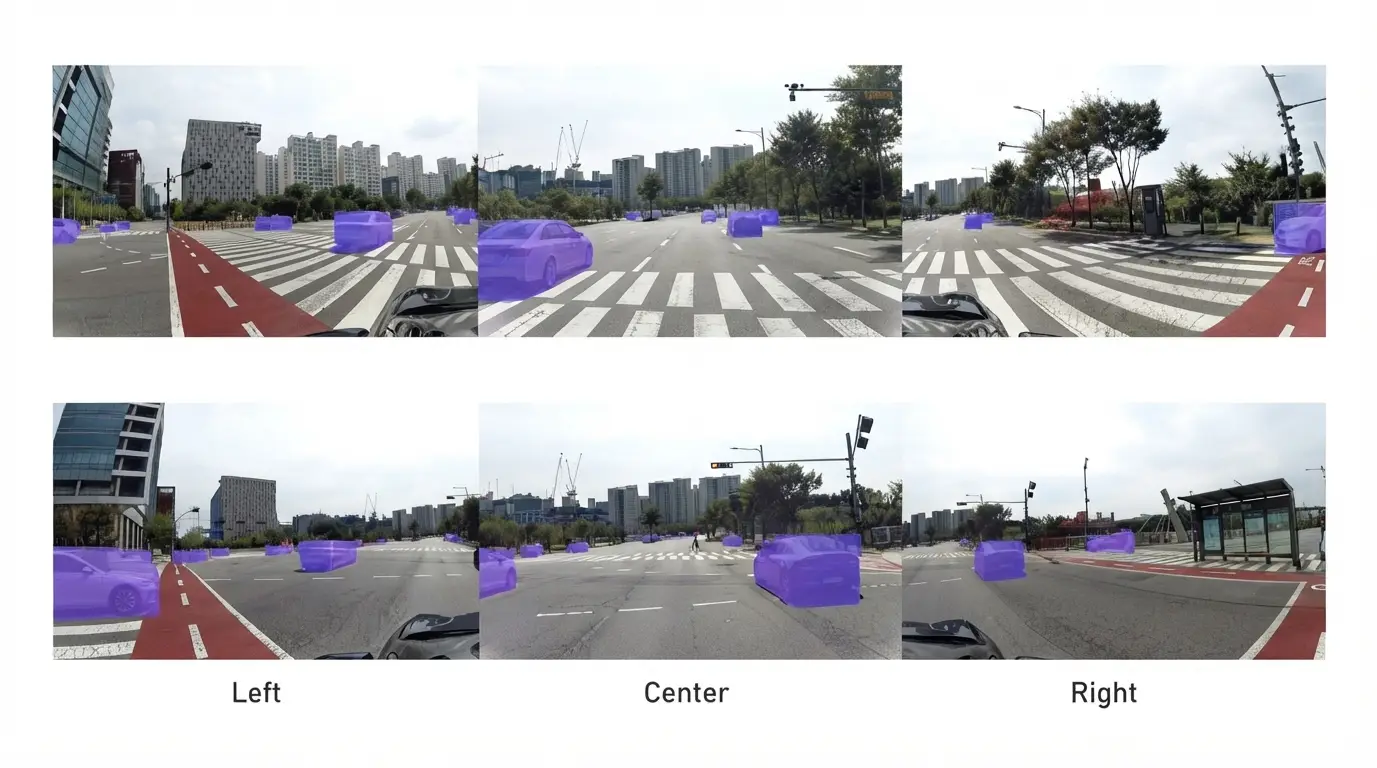
Five families compose a typical nomenclature in driving video annotation. Their requirements differ. Vulnerable road users, pedestrians, cyclists and two-wheelers, the critical class whose omission has the gravest consequence. Vehicles, the majority class whose difficulty lies in volume rather than in recognition. Infrastructure elements, lights, signs and markings, whose annotation often requires a state attribute. Drivable areas, lanes and kerbs, which belong to segmentation rather than to detection. And uncategorised obstacles, objects present on the roadway that fall into no class and must nonetheless be flagged. One practical consequence follows for a video annotation project. The last family is the hardest to define and the most important for safety, a system recognising only known classes being blind to what does not feature among them.Defining the catch-all class
One difficulty deserves separate treatment since it is the least well resolved in this vertical. An obstacle belonging to no known class must nonetheless be flagged. Three formulations exist in video annotation, and they do not produce the same corpus. The open class, which requires annotating any object liable to obstruct circulation without categorising it, a broad formulation whose boundary with the scenery stays vague. The dimensional criterion, which retains any object above a size on the roadway, an applicable rule that misses flat and low objects. And free space segmentation, which inverts the problem by delimiting what is drivable rather than enumerating the obstacles. One important observation follows for a video annotation project. The third formulation resolves the difficulty by construction, since it presupposes no enumeration, and it costs more in annotation while offering the only guarantee of covering the unexpected.The asymmetry of errors
This property governs every video annotation decision in this vertical. An omission on a vulnerable road user and a false detection on a bush bear no comparison. Three consequences follow from that. Quality control must be exhaustive on the critical class and sampled elsewhere, a distribution that contradicts uniform control. Metrics must be reported by class, a global performance drowning the most important class in the volume of vehicles. And the convention must favour over-annotation in case of doubt, an uncertain object having to be flagged rather than discarded. One observation follows. That third consequence inverts the usual practice, where doubt leads to not annotating, and it must be written explicitly failing which annotators apply their reflex.Registration between sensors
This operation conditions the exploitation of a multi-sensor corpus. An annotation produced on a camera must correspond to the same object in the point cloud. Four difficulties contribute to it. Temporal synchronisation, sensors sampling at different rates not supplying views of the same instant. Geometric calibration, whose drift displaces every correspondence. Distinct fields of view, an object visible to one sensor and not the other raising the question of its annotation. And conditions degrading the sensors unequally, night affecting the camera without affecting the LiDAR. One important practical consequence follows. The third difficulty requires an explicit rule, a project having to decide whether ground truth is defined by a reference sensor or by the union of observations, a decision that changes the nature of the corpus.The volume problem
This economic constraint structures driving video annotation more than any other. An instrumented fleet produces a volume no annotation budget covers. Three selection strategies follow. Selection by event, which retains the sequences containing a braking, an avoidance manoeuvre or a handover. Selection by uncertainty, which retains the sequences where an existing model hesitates, a method concentrating effort on what the system does not master. And selection by coverage, which retains the sequences whose conditions are missing from the corpus, weather, hour and geography. One important observation follows for a video annotation project. The second strategy is the most effective and presupposes a model already deployed, which makes it unavailable at the outset and explains why first corpora rest on the other two.Rare cases as the central issue
This property distinguishes this vertical from most vision applications. Average performance matters less than behaviour in exceptional situations. Three consequences follow. A corpus representative of ordinary driving does not prepare for the situations that cause accidents. Rare cases must be sought deliberately rather than awaited, which matches the logic set out for rare species in other domains. And their volume in the corpus must exceed their real frequency, a deliberate over-representation and not a bias to correct. One practical consequence follows. That third consequence conflicts with evaluation, a test set over-representing rare cases not measuring real-condition performance, which requires maintaining two distinct sets.The attributes accompanying each object
Five pieces of information frequently join the box and they multiply the load. Occlusion, whose degree conditions the object’s usability. Truncation by the image edge, distinct from occlusion. Orientation, indispensable for predicting a trajectory and not deducible from an axis-aligned box. Activity state, a stopped vehicle and a parked one calling for different reactions. And observable intent, indicator, brake light or a pedestrian’s gaze direction. One observation follows. The last attribute is the most expensive and the most decisive for anticipation, which makes it a scope trade-off to state explicitly rather than an implicit extension of the work.The conditions to cover
Six dimensions characterise the variability of a driving corpus and their coverage determines the domain of use. Lighting, from full day to night by way of tunnel transitions and backlight. Weather, rain, fog and snow affecting the different sensors unequally. Environment, motorway, dense urban and rural sharing neither density nor the users present. Geography, markings, signage and behaviours varying strongly between countries. Road state, works and diversions producing configurations permanent signage does not describe. And season, whose effect exceeds weather by altering vegetation and the sun’s height. One practical consequence follows for a video annotation project. Those six dimensions multiply rather than add, which explains why a corpus that appears voluminous actually covers a fraction of the situations, and makes an explicit declaration of the conditions covered more informative than the number of hours annotated.What traceability requires
This emerging constraint directly concerns video annotation providers. The type approval of an automated system presupposes documenting the data that trained it. Four requirements follow. A description of the corpus, content, coverage and conditions represented. The annotation method, conventions and control arrangement. A verifiable separation between training and evaluation. And a declaration of limits, situations the corpus does not cover. One important practical consequence follows for a video annotation project. Those four requirements match exactly the practices the preceding series recommended for other reasons, which means a provider already applying them finds themselves compliant with no adaptation effort.What the deployment loop contributes
One organisational feature distinguishes this vertical and it is its principal improvement lever. A fleet in circulation continuously produces situations the corpus did not contain. Four exploitable sources follow. Driver handovers, which signal a situation the system could not handle. Emergency braking, whether triggered by the system or by the human. Disagreements between sensors, a detection present on one and absent from the other pointing at a difficult configuration. And low-score detections, which locate uncertainty with no incident occurring. One important observation follows for a video annotation project. Those four sources produce a continuous flow of high-value sequences, which shifts the question from building an initial corpus towards organising a permanent enrichment, and makes the relationship with a provider durable rather than one-off.What this vertical brought to the others
Four practices born here spread across all video annotation. They are worth naming. Over-annotating critical classes, a principle transposable to any domain where errors are asymmetric. Selection by uncertainty, which replaced random sampling in many contexts. The dual evaluation set, one representative and one enriched in difficult cases. And corpus documentation as a deliverable, a practice the regulatory requirement made standard here before it spread elsewhere. One observation follows. Those four practices apply usefully to projects far more modest than autonomous driving, and their adoption presupposes neither the volumes nor the budgets of this vertical.Quality control adapted to this vertical
Five arrangements answer the asymmetry of consequences and they differ from uniform control. Exhaustive verification of vulnerable road users on a sample, rather than a survey spread across all classes. Targeted search for omissions, which requires full re-annotation of sequences and detects what a check of annotated objects cannot see. Consistency checking between sensors, an object present in one modality and absent from the other signalling an error or a field limit. Verification of transitions, entries, exits and occlusion boundaries concentrating the inconsistencies. And control of incident sequences, whose value justifies systematic rather than sampled verification. One observation follows for a video annotation project. The second arrangement is the most expensive and the only one capable of detecting the gravest failure mode, which justifies reserving it for critical sequences rather than abandoning it for want of being able to apply it everywhere.Uses outside the autonomous vehicle
Four applications share these constraints without aiming at autonomy and they constitute a more accessible market. Driver assistance systems, whose requirements are neighbouring and whose volumes are more modest. Agricultural and construction machinery, which move in unstructured environments with no markings or signage. Intralogistics, trucks and robots operating in warehouses where the vulnerable users are employees. And urban service vehicles, whose mission involves frequent stops and particular attention to the surroundings. One practical consequence follows. Those four applications take up the automotive vertical’s practices at an affordable scale, which makes them realistic entry points for a video annotation provider lacking the capacity to absorb a manufacturer’s volumes.What this context does not forgive
Four video annotation failures carry a gravity here they would not carry elsewhere. An unwritten occlusion convention, which produces inconsistency on the most critical class. A synchronisation defect between sensors, which silently distorts every correspondence. A corpus whose conditions are undocumented, which precludes establishing the system’s domain of use. And a badly defined catch-all class, which leaves the system blind to obstacles it has never seen. That fourth failure deserves emphasis. It is this vertical’s least well handled difficulty, defining what falls into no category being much harder than defining the categories themselves.What this vertical really costs
Five factors determine the load and they explain the gap with an ordinary video annotation project. Object density, an urban scene containing dozens of simultaneous entities to track. The number of attributes per object, each having to be filled across a track’s whole duration. The number of modalities, each sensor adding a view to annotate or to verify. The requirement on the critical class, whose exhaustive control represents a distinct line. And traceability documentation, a deliverable in its own right and not a by-product of production. One practical consequence follows. Those five factors multiply, which produces a cost per minute bearing no comparison with that of surveillance video, a gap a costing should set out rather than leave to be discovered.Approaching a project of this kind
Five questions scope this type of project and they are asked in one meeting. Which sensors and which reference. That answer determines whether ground truth is defined by one sensor or by the union of observations. Is the carrier’s trajectory available. That answer conditions the possibility of working in an absolute frame. Which attributes are required. That answer determines the load more than the number of objects. How are the sequences selected. That answer determines the corpus’s value more than its volume. And is traceability documentation expected. That answer adds a deliverable that cannot be reconstituted afterwards. Those five answers determine the scope, the load and the deliverables. Asking them before starting avoids a voluminous corpus whose coverage is not established.The question that frames the project
One question precedes all the others and it determines the nature of the work. Does the corpus serve to train a system or to demonstrate its compliance. In the first case, coverage and over-representation of difficult cases take priority, and a degree of imprecision dilutes in the volume. In the second, representativeness and reference quality take priority, and an error in the ground truth distorts the demonstration. Those two purposes call for different corpora, different control arrangements and unrelated volumes, which makes their confusion expensive.Three practices to borrow
Three uses from this vertical hold for far more modest projects. Reporting performance by class rather than globally, as soon as one class carries a stake above the others. Maintaining two evaluation sets, one representative and one enriched in difficult cases, rather than a compromise that measures neither. And documenting the conditions covered, information that bounds the domain of use and costs a few lines. Those three practices presuppose neither the volumes nor the budgets of autonomous driving, and their adoption clearly distinguishes a prepared project from an improvised one.What this chapter teaches
One cross-cutting observation deserves closing this examination. This vertical pushed video annotation to its limits and drew transposable practices from it. Three findings compose it. The asymmetry of errors requires an unequal distribution of control effort, a principle holding anywhere all classes do not carry the same consequence. Sequence selection determines a corpus’s value more than its volume, which shifts the issue from production to design. And corpus documentation, imposed here by type approval, matches what reuse requires in any case. That finding matches the one the preceding series established in unrelated domains: regulatory requirements formalise practices that were already rational, and a provider having adopted them by method finds themselves compliant with no transition.Where a smaller provider can compete
One market observation deserves stating, since the scale of this vertical discourages providers who could serve it well. Bulk annotation of driving footage favours the largest operators, and it is not where the difficulty sits. Four segments reward method over capacity. Incident and edge-case sequences, which are low in volume, high in value and demand care rather than throughput. Evaluation corpora, which are small, must be exhaustively verified and cannot be produced by the same process as training data. Convention and reference work, establishing what counts as an occlusion or an obstacle before any volume is produced. And the neighbouring applications set out above, whose volumes suit a provider a manufacturer’s fleet would overwhelm. One practical consequence follows for a video annotation provider. Those four segments share a property: their value comes from judgement rather than from hours, which makes them defensible against scale and makes them the sensible entry into a vertical whose headline volumes are otherwise discouraging.Common mistakes
These failures recur often enough that naming them is usually enough to avoid them.- Interpolating in the image frame when the carrier’s trajectory is available.
- Reporting global performance without isolating vulnerable road users.
- Leaving the doubt convention to the annotators’ judgement.
- Neglecting the definition of the uncategorised obstacle class.
- Not settling which sensor defines ground truth.
- Ignoring temporal synchronisation between sensors.
- Selecting sequences at random rather than by event or by uncertainty.
- Using an evaluation set enriched in rare cases to measure real performance.
- Adding intent attributes without costing the load.
- Building a corpus without documenting the conditions covered.